How to Audit LLM Brand Visibility for Your Lovable Site in 2026
Before signing with an AEO partner, run your own baseline. Here's how to audit LLM brand visibility for a Lovable website — prompts, engines, and the numbers that matter.
A Lovable-built site for a regional accounting firm sat in the top three Google results for “best small business accountant in Denver.” The client was thrilled — until they ran a simple prompt in ChatGPT: “Who should I hire for small business taxes in Denver?” The model named two competitors and described the firm as “a bookkeeping software company,” a category label from 2022. The site ranked. The AI narrative lagged. That gap is why an LLM brand visibility audit matters before anyone signs an agreement with an AEO partner.
This article walks through how to run that audit for a Lovable website in 2026. It is a how-to, not a sales pitch. The value comes from a frozen baseline, a disciplined prompt set, and a clear-eyed read on which signals actually indicate AI recommendability.
Why Audit LLM Brand Visibility Before You Sign With an AEO Partner?
A self-run baseline is the only way to judge a vendor’s claims later. Without it, every future report becomes unfalsifiable — and that protects the vendor, not the buyer. A business that does not know its current mention rate, share of voice, or citation share cannot tell whether a six-month engagement moved anything or simply renamed the metrics.
The problem is structural. Different AEO agencies measure different prompt sets on different engines at different times. One partner’s “87% visibility increase” could reflect a prompt list weighted toward easy branded queries, while another’s “no movement” tracks competitive non-branded prompts. A Lovable site can rank on page one of Google and still be completely absent from ChatGPT answers because retrieval and ranking are different systems. That disconnect is common in AIFun Agency’s work with Lovable clients — the recurring surprise is a site performing well on classic Google while ChatGPT still describes the brand using a three-year-old category label.
A baseline creates a before/after contract benchmark. It also sets realistic expectations on timing. LLM citation shifts are slow. They depend on index refreshes, training data updates, and corroboration from third-party sources. If a partner promises visibility jumps in two weeks, the baseline gives you the evidence to ask what, exactly, changed.
What Does an LLM Brand Visibility Audit Actually Measure?
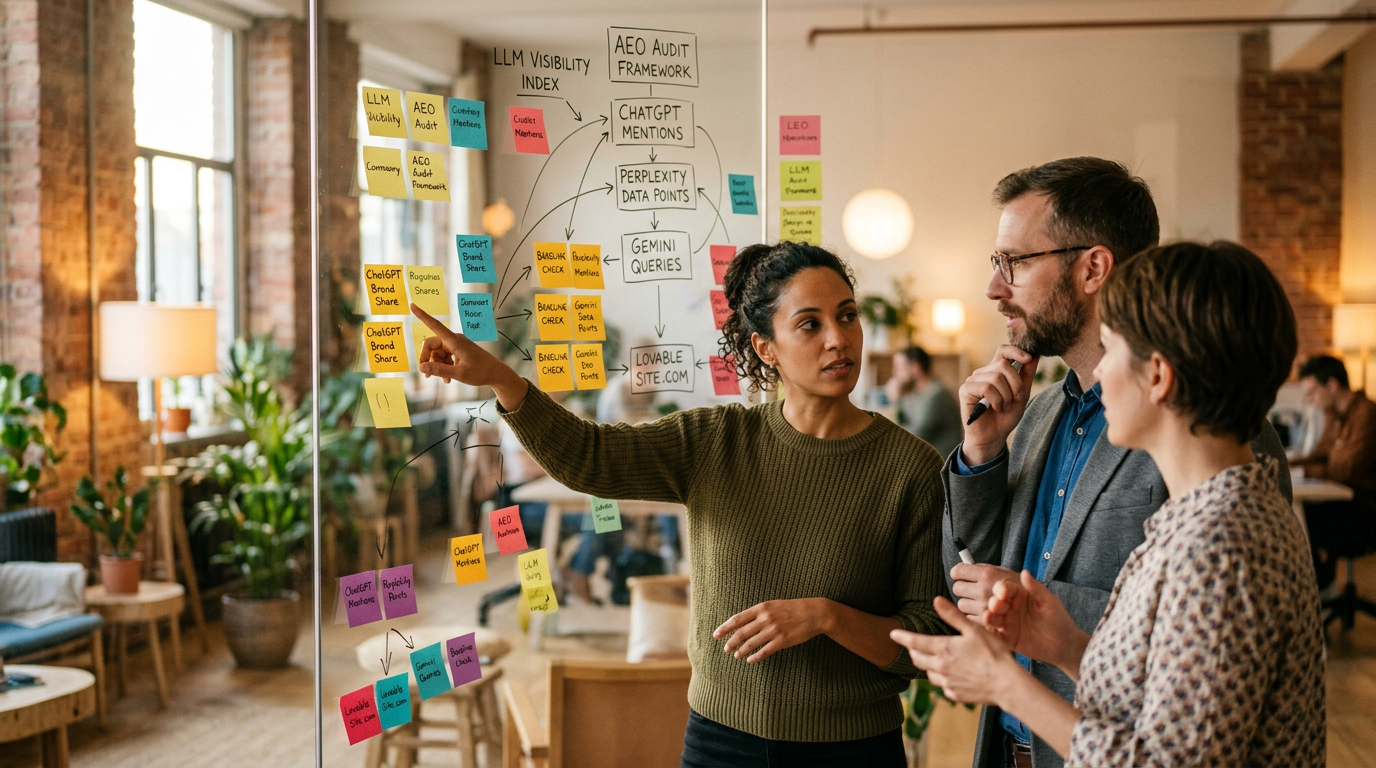
An LLM brand visibility audit tracks four core metrics: mention rate, share of voice, citation share, and sentiment accuracy. Each answers a different question. Mention rate tells you how often the brand appears for a fixed prompt set. Share of voice compares that appearance against named competitors in the same answers. Citation share measures whether the answer links the Lovable domain as a source. Sentiment and framing accuracy capture whether the model describes the business correctly.
Mention rate is the raw numerator. It is meaningless without a denominator — the full prompt set. Share of voice is more useful for positioning: if ChatGPT recommends three competitors and your business appears fourth, that is a presence but not a preference signal. Citation share separates being discussed from being sourced. Perplexity AI surfaces citations visibly; ChatGPT often does not, which makes citation tracking engine-specific.
Position matters more than volume. A first recommendation in a single high-intent prompt is worth more than ten footnote mentions across broad informational queries. In AIFun Agency’s audits of Lovable sites, the team regularly finds brands mentioned in answers but never as the recommended provider. That distinction is what separates visibility from influence.
How Do You Build a Prompt Set That Reflects Real Buyer Questions?
A useful LLM audit is built on non-branded, buyer-intent phrasing — not a list of your own brand keywords. Prompts like “best CRM for solo consultants” or “how do I choose a payroll provider for a 10-person team” reveal whether an AI engine recommends your Lovable site when the user has not named you. Branded prompts have a separate role: they check whether the model describes your business accurately.
Query fan-out matters. One question becomes several sub-queries inside the model’s retrieval pipeline. A prompt like “what should I look for in a managed IT provider” may trigger lookups for security certifications, response times, pricing models, and local reviews. Your Lovable site needs content that answers those decomposed queries, not just the headline question.
The best prompt language comes from real buyer conversations. Sales call transcripts, Reddit threads in your category, and X (Twitter) replies contain the phrasing people actually use. Pull 50 of those phrases. Freeze 30 to 50 prompts so re-runs are comparable month over month. If the prompt set changes, the trend line loses meaning.
Which AI Engines Should the Audit Cover in 2026?
The audit should cover at least five engines: ChatGPT, Perplexity AI, Gemini, Google AI Overviews, and Bing AI Copilot. Each retrieves and ranks differently. One engine is never a proxy for another, and a Lovable site may be recommended by Perplexity while being invisible in ChatGPT.
Perplexity surfaces citations visibly, making it the easiest engine for auditing source-level attribution. ChatGPT often presents answers without clickable links, so auditors must ask follow-up questions like “What sources are you using?” to extract attribution. Gemini behaves differently again, sometimes blending web retrieval with training data. Google AI Overviews pull heavily from classic Google Search ranking signals, which means a Lovable site’s Google rankings, schema markup, and backlinks influence AI Overview visibility in a more direct way than they do in ChatGPT. Bing AI Copilot leans on Bing index quality, which is relevant for a new Lovable domain that may not yet have earned deep Google indexation.
Test logged-in and logged-out where possible. Personalisation, browsing history, and account-level preferences can skew results. A logged-out session is the closest thing to a neutral baseline, but a logged-in session reveals what an actual user with history might see.
How Do You Separate Real Visibility Signals From Vanity Metrics?
Raw mention counts without a fixed prompt set are noise. A report that says “mentioned 120 times in AI answers” but does not disclose the prompt list, the engines used, or the recency of those runs tells the buyer nothing actionable.
Ask for the actual answers, not just a score. The verbatim output lets you verify whether the brand is recommended or merely referenced. Check whether citations point to your Lovable domain or to third parties discussing it. A citation from a review site that mentions your business is not the same as a citation from your own domain.
Cross-reference AI visibility with referral traffic and branded search lift. If ChatGPT visibility genuinely moves, referral sessions from AI engines and searches for your brand name should rise. If those signals stay flat while the report claims a 40% lift, something is being measured imprecisely.
Sentiment accuracy matters more than raw volume for trust. A brand described as “an affordable option for startups” when it actually serves enterprise clients has a visibility problem even if the mention count is high. In AIFun Agency’s work with Lovable clients, inaccurate category labels are often more damaging than absence, because the model confidently asserts the wrong thing.
What Technical Checks on a Lovable Website Should Accompany the Audit?
AI visibility is downstream of site architecture. Before chasing more content, confirm that crawlers can access the Lovable site and that content renders without JavaScript dependence. Lovable’s default stack uses TanStack Start on the front end, and some pages can rely on client-side rendering. If the HTML served to a crawler is an empty shell, no amount of llms.txt or schema markup will fix the gap.
This is where prerendering matters. For client-heavy pages, use Prerender.io or a similar server-side rendering solution so AI crawlers receive fully populated HTML. Check the rendered source yourself — view-source is the fastest audit tool available.
Schema markup on services, FAQs, and organisation details gives AI engines structured signals about what the Lovable site does and who runs it. A published llms.txt and clean internal linking give crawlers a clear path through the site’s priority pages. Google’s documentation on AI features explicitly connects structured data and index quality to how content appears in generative search features. For the Lovable-specific configuration, setting up llms.txt on a Lovable site walks through the implementation.
Page speed and Core Web Vitals round out the technical check. Retrieval favours fast, stable pages. The Lovable SEO checklist covers speed, rendering, and indexation in Lovable’s specific context, and web.dev provides the measurement framework. If the site fails basic crawlability, the audit should flag that as the first fix before any content or authority work.
How Do You Vet an AEO Partner's Report Before You Pay?
A vendor’s report is only as useful as its methodology. Demand the raw prompt list and verbatim answers for every engine tested. If a partner will not share the actual prompts, the numbers cannot be reproduced — and unfalsifiable reporting is a red flag.
Ask how they will implement fixes on Lovable specifically. Generic SEO tasks — “write more blog posts,” “build backlinks” — are not the same as AEO work on a Lovable site. The partner should be able to speak to Lovable’s rendering model, llms.txt, schema implementation, and answer capsule formatting. If they talk only about WordPress plugins, they are selling a service you cannot use.
Clarify reporting cadence and which engines are included. A monthly report across five engines with frozen prompts is a professional deliverable. A quarterly report with “selected highlights” is not. Ask what a failed month looks like and how they diagnose it. A good partner defines failure in advance: no movement in citation share, a drop in mention rate, or inaccurate brand framing on key prompts.
Require competitor tracking, not brand-only reporting. Brand-only reports create the illusion of progress by ignoring the competitive landscape. If your Lovable site gains one new mention but three competitors gain five each, share of voice fell.
What Should Your First 30 Days Look Like After the Baseline?
The first thirty days after a baseline audit should be about fixing what blocks retrieval, not adding new pages. If the audit found rendering gaps, schema errors, or crawlability issues, those are the priority. Content work on a Lovable site that AI crawlers cannot read is wasted effort.
After fixing plumbing, publish extractable answer capsules and FAQ blocks on money pages. The answer capsule format is the core of writing answer capsules on Lovable pages — a direct, standalone answer to the user’s question placed immediately under the heading, structured so an LLM can lift it cleanly. These capsules signal relevance to both Google’s AI features and third-party models.
Strengthen third-party corroboration. AI engines are more likely to recommend a Lovable site when independent sources — reviews, directories, industry publications — describe the business accurately. One well-placed industry mention can shift framing more than ten self-published blog posts.
Re-run the frozen prompt set at 30 and 90 days. Do not chase daily fluctuations. LLM outputs are non-deterministic; run each prompt three times per session and record the mode. Document deltas in mention rate, share of voice, citation share, and sentiment accuracy so the partner relationship stays accountable. DataJelly and similar tools can automate some of this recording, but a simple spreadsheet works.
From Baseline to Citable Asset
An audit is not a one-time event. It is the control condition that makes every later AI visibility claim testable. A Lovable website that ranks on Google but is described by ChatGPT using an outdated category label has not failed; it has simply not yet been optimised for the retrieval layer that sits above classic search.
The path from baseline to citable asset runs through technical crawlability, structured answer capsules, and third-party corroboration. The prompt set stays frozen. The engines stay fixed. The metrics stay boring and comparable. That discipline is what separates a defensible AEO engagement from a monthly report full of moving targets.
AIFun Agency uses this exact baseline framework when working with Lovable clients, because the team has learned that you cannot improve what you refuse to measure. The surprising part is never the final ranking. It is how much of the gap was visible in the first week, before anyone spent a dollar on outreach.
Want ChatGPT and Google AI Overviews to recommend your business instead of a competitor? See how the AEO / GEO Dominator system works → https://aifunn.com
In AIFun Agency's work with clients building Lovable websites, the teams that ship answer-capsule sections under every H2 are the ones that start earning AI citations within a few weeks. ## Sources
Frequently asked questions
How do I check if ChatGPT recommends my business?
A practical check involves asking ChatGPT directly: "Which [category] businesses in [city] do you recommend?" Then note whether the brand appears, how it is described, and whether the answer cites the website. For deeper analysis, run the same query across new chat sessions, compare responses in Perplexity AI and Bing Copilot, and test variations like "best [service] near me." Because ChatGPT responses vary, documenting multiple runs and saving transcripts creates a baseline before any optimization work begins.
What is an LLM visibility audit and what should it include?
An LLM visibility audit measures how often and how favorably large language models mention a brand across AI search tools. It should include query mapping around buyer intent, share-of-mention scoring against competitors, sentiment and accuracy checks, citation source analysis, and a technical review of the website's crawlability, structured data, and llms.txt file. For Lovable sites, the audit should also verify server-side rendering and whether dynamic content is visible to AI crawlers, since those factors heavily influence whether models can retrieve and cite the site.
How much does an AEO audit usually cost in 2026?
In 2026, AEO audit pricing varies widely by scope. Basic self-serve audits using query tracking tools may cost from a few hundred dollars, while practitioner-led audits that include competitor share-of-mention analysis, citation diagnostics, and technical recommendations typically range from $1,500 to $7,500 depending on market size and tooling depth. Agencies focused on Lovable sites often bundle the audit with implementation, which changes the total. Buyers should request a sample deliverable and clarify whether pricing covers only reporting or also includes fixes and retesting.
Can a Lovable website rank in Google AI Overviews?
Yes. Lovable websites can appear in Google AI Overviews when the content is structured as clear answer capsules, the site is server-side rendered so Google can fully process it, and authoritative sources link to it. Because AI Overviews pull from indexed pages, a Lovable site must first perform well in traditional search. Adding FAQ schema, clean headings, and original data strengthens eligibility. AIFun Agency's work with Lovable clients shows that compact, question-based content often gets cited more readily than long marketing pages.
How long before AI search visibility improves after an audit?
Early changes can appear within two to four weeks if the audit identifies quick fixes like schema markup, llms.txt, or crawlability errors. More meaningful gains in ChatGPT and Perplexity citations usually take eight to twelve weeks, because AI systems need time to re-crawl, re-index, and update training or retrieval patterns. Google AI Overviews may respond faster once pages rank. Sustained visibility requires ongoing content updates and backlinks; a one-time audit alone rarely produces durable results.
Do I need schema markup on my Lovable site for AI citations?
Schema markup is not strictly required, but it strongly improves the odds. Structured data helps search engines and AI crawlers understand business type, services, FAQs, pricing, reviews, and authorship. On Lovable, adding JSON-LD schema through custom code or an integration makes a site easier to retrieve and cite accurately. While ChatGPT and Perplexity can read plain text, schema reduces ambiguity and supports rich results that feed AI Overviews. A proper audit should check for missing, invalid, or duplicated structured data.
Should I audit Perplexity and ChatGPT separately?
Yes. Although both are AI answer engines, they retrieve and rank sources differently. ChatGPT tends to synthesize from its training data plus live browsing, while Perplexity explicitly lists source citations for each claim. An effective audit tests the same prompts in both tools, records share of mention, compares citations, and notes where answers diverge. Because recommendation behavior also differs by geography and session history, testing each platform separately creates a more reliable baseline before hiring an AEO partner.
Share this article
Help others discover great content
See How AI Sees Your Business
Get your free AI Visibility Score and find out whether AI is recommending your business — or sending customers to your competitors.
Keep reading
All articles →
How Long Does It Take to Get Mentioned by ChatGPT? (2026 Reality)
ChatGPT citations rarely arrive in weeks. Here's what actually gates the timeline — crawl lag, entity consolidation, and retrieval recency — and how to shorten it.
Whitelabel GEO Audits on Lovable Sites: What Agencies Get Wrong
Most whitelabel GEO audits hand clients a PDF of generic fixes. On Lovable sites, the real gaps sit in rendering, schema, and answer capsules — and in what the audit never measures.
Do You Need Brand Mentions in ChatGPT? A 2026 Decision Test
A fast triage framework for deciding whether ChatGPT brand mentions deserve a dedicated campaign or a few structural fixes — before you commit budget in 2026.